Design judgment
The question
A screen can look fine and still be wrong in use. So what tells you it is wrong?
The question came back on every project. These six are the evidence that contradicted me, and what I changed because of it. The numbers are the ones on each project's own page.
01 – Twelve reviewed features fell over on one screen
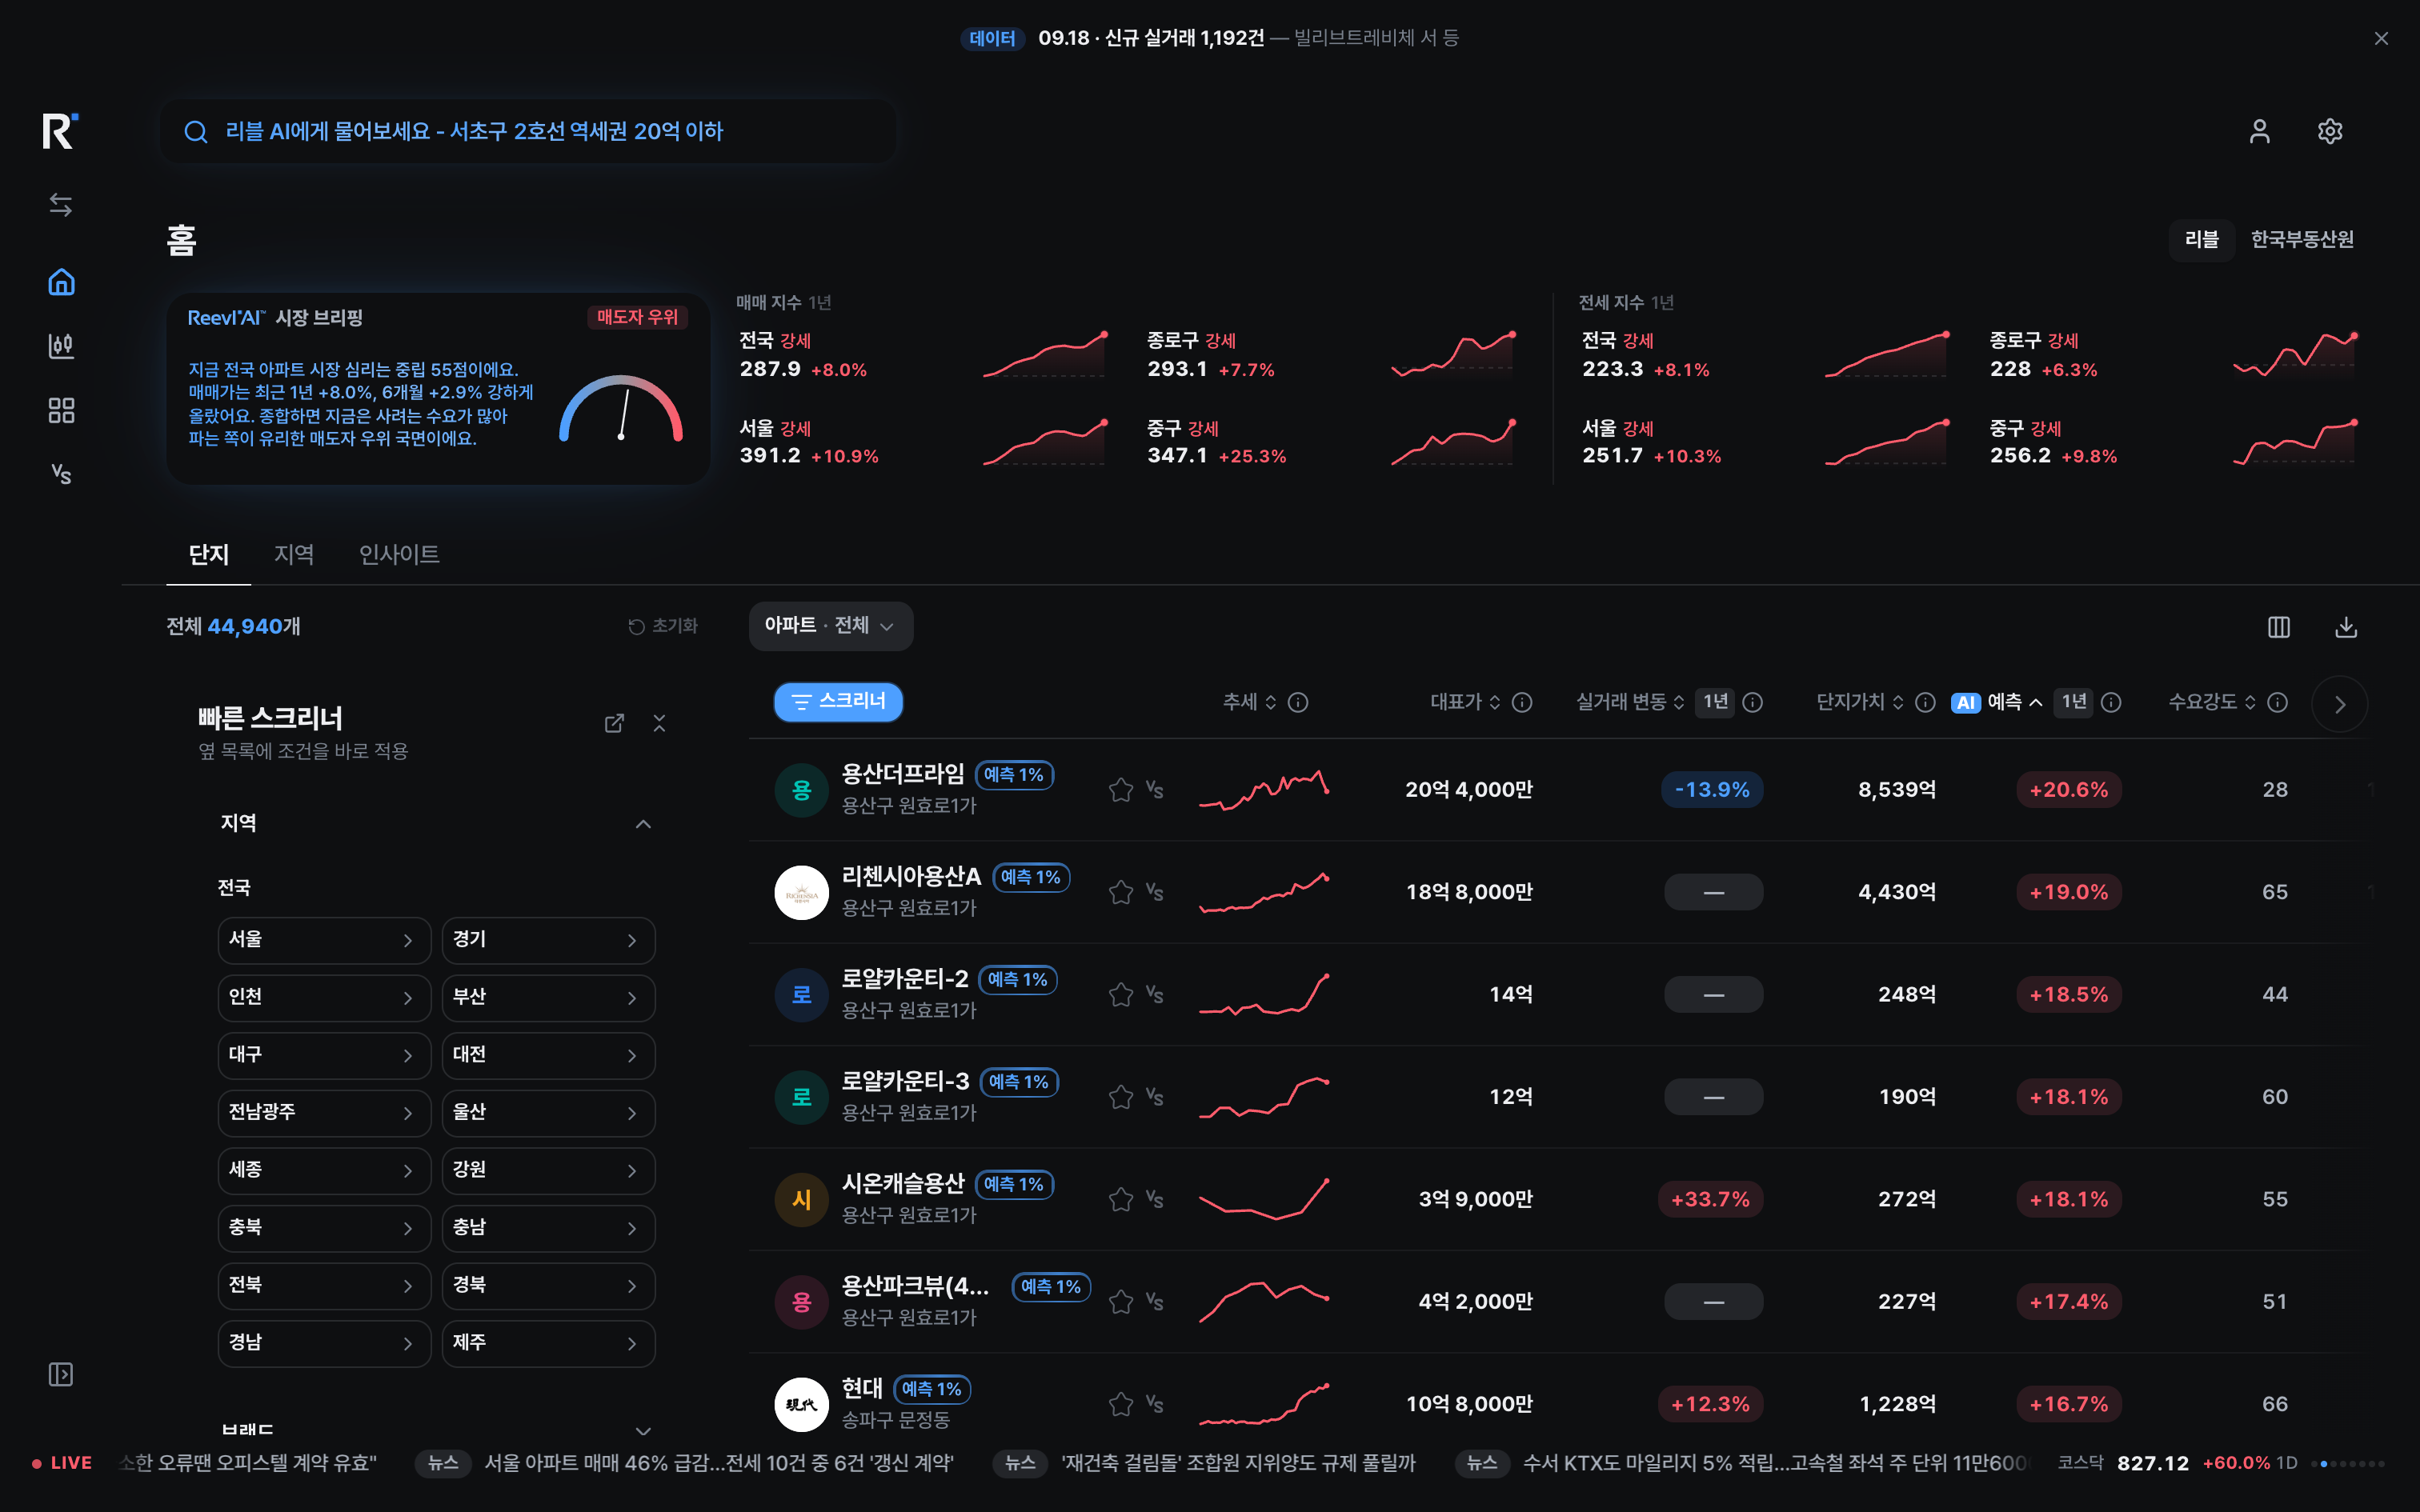
On 27 August 2026 I shipped twelve features to Reevl in a day. Each had passed review. Within hours bounce went from 24% to 62% and time on site from 226 seconds to 40. Clarity recorded 36 rage clicks – the only day in the observation window with any (measured, GA4 and Clarity).
I watched the session replays. The features were not the problem; the screen was. Controls that looked interactive and were not. A filter that reset the view. Density added without a reading order. Six causes, found and fixed.
Rage clicks 0 by 29 August, dead clicks 98 → 18. Bounce 29% and dwell 115 seconds by 1 September (measured).
- What it contradicted – that a screen which passes review is fine. Each of the twelve features was right; the result of putting them on one screen was wrong.
- What changed – a review answers "does this look good?". So I ship with the instrument that can contradict me switched on.
02 – Numbers I could not stand behind, removed
Reevl's one-year outlook ranked complexes with an information coefficient of 0.19, positive in 93% of quarters. Beyond two years, the per-complex IC was 0.01. A number that cannot be right.
A figure printed in won reads as certainty whatever the caption says. So long-range forecasts show no amount at all. They are given only at the regional level, which held under walk-forward validation (IC 0.16).
The validation score fooled me once too. Future information leaked into the label calculation and doubled the IC. Fixed with FEATURE_LAG=2. Of five model upgrades, four were rejected once measured.
- What it contradicted – that a good validation score can be trusted as it stands.
- What changed – precision is a visual claim. Where the data cannot carry it, the screen does not make it.
03 – An amount I don't know stays blank
Commit collects grant notices whose API carries no funding amount; the amount lives in a separate business-information API. So an amount shows only where the match is certain: 2,595 of 11,757 notices, 22.1% (output).
Filling the gap with a model raises coverage and lowers trust. One wrong amount costs more trust than several right ones return. Where the rules are unsure the figure stays empty and the reader is sent to the original. There are no runtime LLM calls at all; summaries and eligibility checks are rule-based.
The same judgment applied to logos. A favicon service returned blank icons as "success", so only 116 hand-checked agency logos are used.
- What it contradicted – that a success response from automation means the output is right.
- What changed – a default value is an assertion. If I don't know, the field stays empty.
04 – Red is up, blue is down, everywhere
Green-for-up is the international habit. Korean market readers read red as rising, so red is correct here.
A convention is information, not decoration. Left to whoever builds the next screen, it eventually breaks. So direction colours exist only as design tokens (up · down), and green never means rising anywhere in the product.
The tokens were extracted back out of the code into the Figma library: 140 variables, 28 styles, 23 components (v1.0, 2026-09-17, output). Adoption is measured on every build – colour 98.5%, type 100%, z-layers 95.2% (measured by ds_scan).
- What it contradicted – that consistency holds if you try hard to hold it.
- What changed – the rule now lives where it cannot be broken.
05 – Two colours that looked fine and failed
In SAI, secondary text measured 4.49:1 and white on the accent 3.88:1. Both were below WCAG AA, and both looked fine to me. They became 5.05 and 4.77 (measured).
So the eye was replaced by a check: 32 Playwright tests on desktop (1440×900) and mobile, any console error fails the run, axe checks WCAG 2.1 AA (output).
- What it contradicted – that looking acceptable on a good screen means passing.
- What changed – where a measurement exists, it decides. The eye is a second opinion.
06 – Function-centred to moment-centred
The KTX in-carriage displays were organised by function. Next station, arrival time, transfers, facilities and notices all carried the same weight, so a passenger had to search each time.
I ranked the content by the moment it belongs to: before boarding, on the move, after arrival. The next station, arrival time and service state are sized to read from across the carriage; everything else steps back. When the doors open, only the side they open on is large. Korean and English share one layout system, and station names follow one rule across four scripts.
Nothing was added. Only the order was decided.
- Not verified – viewing distance and lighting in a real carriage, and testing with passengers. There is no number saying this is easier to use.
Judging what a model produces
I pair-program with a model daily and operate products whose content is partly generated. The same questions apply.
- The system decides, not the generation. When generated screens stepped outside Reevl's tokens, I changed the tokens, not the screen.
- Don't put a model where it can be wrong. Commit calls no model at runtime. Not creating the place where it can be wrong was cheaper than correcting wrong answers.
- Generated proposals carry their evidence. Every SAI suggestion card carries the utterance it came from, and nothing becomes a note until a person accepts it.
- Check the artefact, not the log. A pipeline of mine reported success for six weeks while blog publishing had stopped, and a broken monitoring filter counted 11,891 server errors as zero. Monitoring now watches what was published.
The four questions
- What is this screen for? Name the one thing someone came to do, then check whether it is the easiest thing to do.
- What is largest? Size, weight and position are all claims about importance. If everything is the same size, the design has no opinion.
- Is colour carrying meaning? Up and down, normal and delayed – or decoration.
- What can be measured? Contrast, focus order, rage clicks, dwell time, information coefficient. Taste ends where a measurement begins.
What I can't show yet
All six came from products I built. Reevl and Commit are solo; on SAI I owned UX, the design system and the frontend in a team of three. Whether the same judgment holds on someone else's screen, I have no evidence for yet.